Rithin Nagaraj researcher-in-training

Hi! I’m Rithin, I study computer science and engineering at PES University, Bangalore. Right now I’m a research intern at Lossfunk and an independent research collaborator working with Maksim Anisimov, a PhD Candidate at Imperial College London.

My work revolves around multiple things: environment design, optimization, world models, interpretability, bioml, and reinforcement learning. Although, they all have a common underlying thread (1) how do models behave when with different kinds of data and optimization (2) how do we make models more trustable (3) how can we make our external components (everything except the model like harness and environments) safer against misaligned models. Apart from my research, I’m a geography geek (avid geoguessr player) and have fun doing debates sometimes.

I also write long-form explainers on the blog.

interests: reinforcement learning, AI safety and control, continual learning, world models, interpretability.

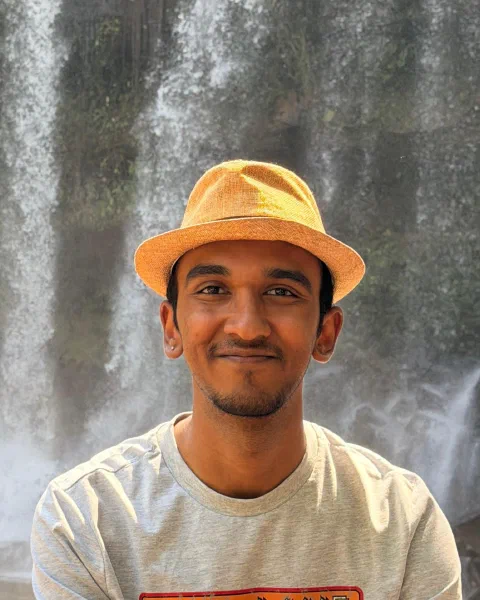
Rithin Nagaraj, smiling, in a straw fedora in front of a waterfall
photo from a waterfall in rural cambodia

rithin[dot]nagaraj[at]gmail[dot]com
pes university, bangalore

publications

Pharmacokinetic SSMs for Haemodynamic Collapse Prediction

AIiH 2026 · ★ Best Paper Nominee (top 3%)

doiarxiv
details
  • Architected a Mamba-based selective state space model to forecast intraoperative hypotension 5 to 15 minutes in advance, achieving 0.7360 AUROC and a 2.73-fold AUPRC lift over random guessing.
  • Engineered Propofol and Remifentanil effect-site concentration trajectories as explicit inputs, preventing a 13.9% AUPRC drop compared with haemodynamics-only baselines.
  • Quantified lead-gap contamination in prior evaluation setups, with strict temporal boundaries reducing apparent AUROC by 16.7% compared with the less constrained evaluation.

CAP-Adam: Inspectable Protection for Continual Learning

Under review at TMLR

details
  • Proposed a continual learning optimizer that modulates parameter updates by their importance to previously learned tasks, outperforming AdamW and established baselines including Elastic Weight Consolidation (EWC).
  • Achieved approximately 90% retention across 40 unique tasks while maintaining 91% mean current-task accuracy over 200 sequential tasks on Permuted MNIST with an MLP-300 model.
  • Showed that optimizer hyperparameters systematically control the stability–plasticity trade-off, enabling controlled studies of knowledge retention and adaptation.

Comparing Latent Concept Formation in SSMs and Transformers via SAEs

arXiv preprint, 2026

arxiv
details
  • Mapped feature-level correspondences between Mamba-130m and Pythia-70m using sparse autoencoder dictionaries over 10M text tokens, finding no evidence of architecture-exclusive Dark Matter features.
  • Identified monosemantic landmark features in Mamba’s recurrent hidden state and hypothesized that they act as periodic state resets that compensate for the absence of global positional attention.

in progress

Continual RLVR and Safety-Support Collapse

Imperial College London

code
details
  • Asking whether training a 3B Qwen model on a sequence of harmless tasks with RL from verifiable rewards (RLVR) can quietly make useful, safe answers on earlier tasks unreachable, even while task accuracy and aggregate safety metrics look stable.
  • Measuring how many rollouts corrective RLVR needs before earlier tasks give a useful learning signal again, to see whether continual training makes safety fixes more expensive.

Adversarially Trained Container Design for LLM Agent Control

Lossfunk

code
details
  • Training a designer model against LLM agents to write Docker configurations that stop a possibly misaligned agent from escaping or causing harm, without blocking the harmless work it is there to do.
  • In a first sanity check with Qwen3-30B-A3B, DeepSeek-V4-Pro and GLM-5.3 as agents (4 routes to harm, ~5,000 possible configurations), a simple softmax policy found a setup that was both safe and useful within 20 episodes.
  • Next: adding more independent routes to harm and opening up a much larger configuration space.

Confounding in Learned World Models for Anesthesia Dosing

PES University

code
details
  • Clinicians adjust doses in response to what they see, so a model trained on recorded surgeries can pick up those reactions instead of how the drugs actually work. Testing whether world models fall into this trap, since RL dosing policies would be trained inside them.
  • Trained 25 models (GRU, Transformer, RSSM, a 5-RSSM ensemble, and a hybrid where doses act only through pharmacokinetic–pharmacodynamic equations; 5 seeds each). The black boxes predict well: 6.9–7.2 five-minute BIS error, 27–29% better than pharmacology alone.
  • Early counterfactual tests suggest they learned only part of the story: drug effects point the right way but are just 12–21% as strong as pharmacology predicts and arrive 3–7 min late. The hybrid recovers ~72% of the expected effect with correct timing, at a 12% cost in BIS accuracy.

experience

projects

Stable-Drift Re-implementation

Apr 2026

code
details
  • Re-implemented the ICCV 2025 latent drift-guided replay method on CIFAR-10, selecting exemplars by representational change under domain adaptation and validating that drift-based selection reduces forgetting compared with random replay.

Probing Compositional Limits in Object-Centric Learning

Jan 2026

code
details
  • Built a frozen Slot Attention plus relational graph pipeline for unsupervised object-part binding, using connected components and pairwise relations to bridge over-segmented object parts.
  • Achieved 0.775 F1 on texture-flattened PartImageNet++ and used zero-shot transfer from vehicles to quadrupeds to probe how strongly learned relations depend on domain-specific latent geometry.

World Models Re-implementation

Nov 2025

code
details
  • Reproduced the complete VAE, MDN-RNN, and CMA-ES controller pipeline from scratch on CarRacing-v0, including random rollout collection, latent representation learning, sequence modeling, and controller optimization.

writing

toolbox